sys.statusOpen to SWE roles & internships

I build AI infrastructure andbackend systems that don't fall over.

Full-stack & AI Engineer (B.Tech, 2027). Built an LLM gateway with semantic caching, a Go notification system handling 9,200+ req/s, and shipped features to Graphify (120K★) and Checkmate (11K★).

Move your cursor... see if you can uncover the secret.

toolkit.yaml
1languages: [Go, Python, C++, TypeScript, SQL]
2backend_ai: [LLMs, Claude, gRPC, Redis, pgvector]
3infra_ops: [Docker, AWS, Prometheus, Jaeger]
4ai_tools: [MCP, Codex, Langfuse]
5web: [Next.js, Tailwind CSS, Node.js]|

gRPC inworker poolRedisqueuefan-out
Featured

High-Throughput Notification Broker

A decoupled 3-tier microservice notification engine in Go, built to survive worker crashes and network drops without losing a single message.

  • Sustained 9,200+ requests/sec (552k in 60s) with 13.8ms average latency during intensive stress testing.
  • Engineered a zero-loss worker pool with 200 concurrent goroutines using Redis BLMOVE for atomic queue draining.
  • Implemented exponential backoff, jitter, and a Dead Letter Queue (DLQ) archiver that drains to AWS S3.
  • Stress-tested resilience via intentional TCP socket exhaustion to verify 100% message delivery.
#go#grpc#redis#aws#prometheus#jaeger
requestsemanticcachepgvectorGatewayOpenAIAnthropicGemini
Featured

OmniRoute – Multi-Provider LLM Gateway

A resilient AI gateway that dynamically load-balances traffic across OpenAI, Anthropic, and Gemini to decouple clients from single-provider outages.

  • Architected a multi-provider LLM gateway in Go, exposing a unified OpenAI-compatible API with dynamic routing, graceful model fallback, and real-time token cost tracking.
  • Implemented a Semantic Cache using OpenAI Embeddings and pgvector for cosine similarity lookups, slashing P95 latency by ~80% and reducing API spend.
  • Built zero-dependency resilience primitives for AI workloads: a sliding-window circuit breaker (Closed → Open → HalfOpen) and a mutex-guarded token bucket rate limiter.
  • Engineered an automated LLM evaluation engine executing concurrent fan-out runs to measure Time To First Token (TTFT), cost per 1K tokens, and response quality.
#go#python#pgvector#prometheus#langfuse#docker
Meta Clash screenshot 1

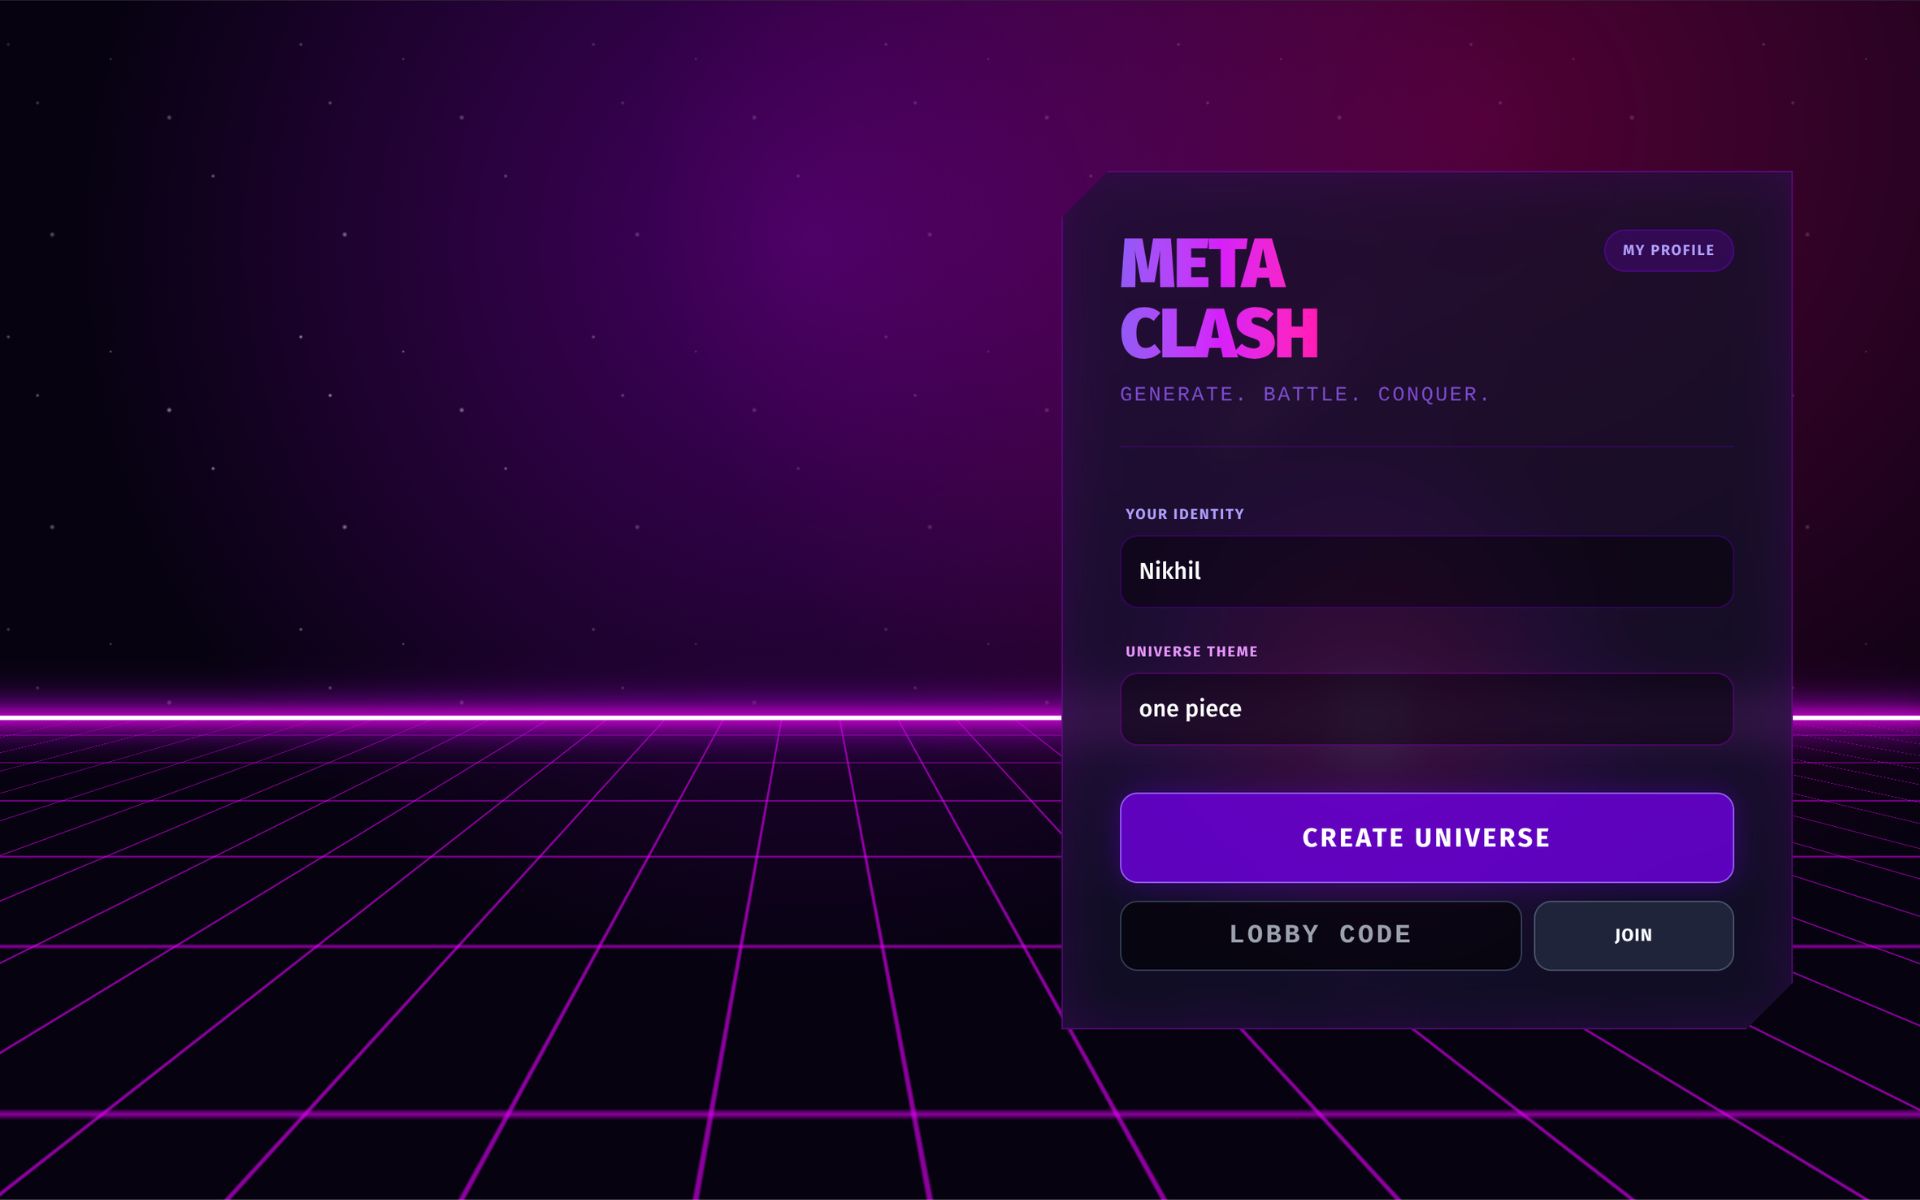
Meta Clash

A server-authoritative real-time multiplayer game back-end managing state lifecycles and deterministic combat.

  • Designed a hexagonal architecture with a 3-state finite state machine (FSM) for 4 concurrent players.
  • Built a WebSocket hub using goroutines, channels, and sync.RWMutex for thread-safe state broadcasting.
  • Implemented a 54s ping/pong heartbeat to ensure connection stability and detect drops.
#go#next.js#postgresql#websockets#docker
Nikhil Saxena

I'm a Full-Stack & AI Engineer graduating in 2027. Most of my work sits at the infrastructure layer — LLM gateways, message queues, distributed tracing — but I also build the interfaces on top when a feature needs one, like the incident-history UI I shipped for Checkmate.

Open source is where I test myself against real codebases. I've shipped fixes and features to Graphify (120K★, 7M+ downloads) and Checkmate (11K★). Outside that, I'm usually deep in DSA, Go, or LLM evaluation work.

India · Open to remoteFueled by musicRelaxed finessing